> For the complete documentation index, see [llms.txt](https://developer.harness.io/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://developer.harness.io/ai-security-use-ai-security-ai-firewall-policies/use-ai-security/ai-firewall-policies.md).
# AI Firewall Policies
Learn how to configure AI Firewall threat types and custom rules to detect prompt injection, sensitive data exposure, and other threats to AI applications.
Updates (October 2026 to December 2026)
* *November 2026:* Updated the topic to add information about rate limiting for MCP servers and tools, the new compute conditions, and the new Agent Access Control rule that controls which agents can access MCP servers and tools. For more information, see [Create custom AI firewall rules](#create-custom-ai-firewall-rules).
* *October 2026:* Updated the topic to add information about the new threat type for exploit payloads in LLM-generated output, and the new MCP protection threat types that detect PII exposure in tool responses and unusually large tool responses that may indicate excessive data exposure. For more information, see [Understand AI threat types](#understand-ai-threat-types).
**Older Updates**
* *September 2026:* Updated the topic to add information about the MCP threat rules. For more information, see [Understand AI threat types](#understand-ai-threat-types).
* *August 2026:* Updated the topic to add information about the Toxic threat type and AI Sensitive Data Protection to reflect expanded coverage across both prompts and responses. For more information, see [Understand AI threat types](#understand-ai-threat-types).
AI Firewall helps you secure AI-powered systems against emerging threats targeting large language models (LLMs), generative AI applications, and APIs that contain AI-native data. As you increasingly embed AI into your workflows, these models can become targets for attacks from malicious users who attempt to manipulate prompts, extract sensitive data, or influence model performance.
The **AI Firewall** page lets you define and manage policies to protect your AI assets and services against malicious activity. These policies enable you to detect and monitor threats specific to AI applications, such as prompt injection, model manipulation, or data exfiltration attempts. AI Firewall policies help ensure that your AI assets, such as models and integrated LLMs, operate securely within your applications by automatically identifying high-risk behavior and enforcing custom protection rules.
AI Application Protection Policies
## What you will learn from this topic
By the end of this topic, you will be able to understand:
* The concept of AI Firewall policies and how they help.
* The way to access the AI Firewall policies page.
* The default threat types and how to manage them.
* The steps to add a custom AI Firewall policy.
***
## Before you begin
Before you understand AI Firewall policies, make a note of the following:
* Make sure you have the *Settings* RBAC permissions under **Module Level Access** → **Protection** to create the rules.
***
## Understand AI threat types
By default, Harness RPA provides multiple AI threat types that you can use to categorize and respond to different risks in AI systems. The following are some threat types:
| Threat Types | Description |
| -------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Prompt Text Evasion and Misdirection | Detects attempts to bypass safety and moderation controls by disguising prompt content. Attackers may use alternate languages, invisible characters, or intentionally ambiguous phrasing to hide malicious intent and generate restricted output. |
| Toxic Unsafe Content | Detects toxic and unsafe content, hate speech, harassment, self-harm content, and other harmful language that can show up in your AI application, whether an attacker provoked it or not. Harness RPA detects it using both signature-based rules and machine learning (ML) models, so coverage keeps pace as these patterns evolve. |
| MCP Schema Validation | Validates MCP request and response payloads against the expected schema and flags deviations. |
| MCP IP/ Geo Detection | Detects and flags MCP requests originating from unexpected IP addresses or geographic locations. |
| MCP Tool Output Information Disclosure | Detects when MCP tool responses expose sensitive or unintended information, such as credentials, internal data, system details, or other confidential content. |
| MCP Unauthenticated Access | Detects attempts to access MCP tools or resources without valid authentication, helping prevent unauthorized users or applications from interacting with MCP services. |
| Exploit Payload in LLM output | Detects potentially exploitable payloads in LLM-generated output, including SQL injection, command injection, template injection, and path traversal patterns. |
| PII Detected in Tool Response | Detects when an MCP tool response contains personally identifiable information (PII), such as email addresses and phone numbers, that may expose sensitive data in bulk and is different from the usual PII in the response. |
| Tool Call Response Explosion | Detects when an MCP tool response is significantly larger than expected based on the tool’s learned response-size baseline, which may indicate excessive data exposure or a potential data dump. |
| AI Sensitive Data Protection | Detects sensitive data, including personally identifiable information (PII), can surface in an AI prompt or in the model's response, exposing regulated or confidential information you never intended to share. Harness RPA identifies this data on both sides of the conversation, so exposure does not slip through just because it appears in a response rather than a prompt. Harness RPA supports a limited set of high-confidence data types for this detection. |
| Prompt Injection | Detects prompts designed to manipulate model behavior by overriding system instructions or introducing unauthorized directives. These attacks often attempt to extract sensitive information, bypass safeguards, or force the model to perform unintended actions. |
| Model Governance | Detects usage that deviates from approved model governance policies, including unauthorized model selection, configuration changes, or version drift. This helps ensure AI usage remains compliant with organizational security and regulatory requirements. |
| Agent Access Control | Enables granular access governance for AI agents by defining and enforcing policies that control which MCP servers, tools, skills, and actions agents can access based on their identity and permissions. It evaluates agent requests at runtime to detect and flag unauthorized access attempts, including requests to MCP servers, tools, or LLMs that the agent is not permitted to use. |
| Code Detected in Prompt | Detects prompts containing executable code or exploit patterns, such as XSS payloads, SQL injection attempts, shell commands, or runtime-targeted scripts. These inputs may indicate attempts to generate exploit code or probe unsafe model behaviors. |
| AI Rate Limiting | Detects unusually high volumes of requests to AI API entities or MCP entities within a defined time window. You can count requests per user, per endpoint, per tool, or per server, or apply one global limit. This helps you identify automation abuse, misuse, and denial-of-service attempts, and helps maintain consistent system availability and performance. |
| AI Input Explosion | Detects prompts intentionally structured to expand recursively or generate excessive token usage. These inputs attempt to exhaust processing resources, increase latency, or degrade model performance across AI workloads. |
Each threat type includes a set of rules you can manage to align with your AI security posture and requirements. While Harness RPA provides predefined rules, you can also define custom rules according to your specific requirements. Go to [Create custom AI Firewall rules](#create-custom-ai-firewall-rules) for more details.
***
## Key features
The following features are available in the AI Firewall tab:
| Features | Description |
| ----------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| Threat Type/Threat Rule List | Threat Types categorize the predefined and custom AI Firewall rules by default, such as *Prompt Injection*. Go to [Create custom AI Firewall rules](#create-custom-ai-firewall-rules) for information on creating custom AI Firewall rules. |
| Threat Type/Threat Rule Information |
Displays the following details for each threat type and rule:
Info: Click the Info (:circle-info:) icon to view the Description, Impact, Mitigation, and References of a threat type or rule.
Labels: Classify the threat rule based on OWASP API security trends and CWE references.
|
| Severity Levels | Displays the severity assigned to issues detected by the rule, indicating their impact on your application. |
| Actions |
Displays the actions Harness RPA should take against the threat detected by the rule. The following actions are available for each rule:
Monitor: Logs and monitors the threats, but does not block requests.
Disable: Turns the rule off, so Harness RPA does not monitor it.
Mark for Testing: Tests the behavior of rules by generating security events without affecting the threat score of the actors.
This is the default setting for any new and/or updated rules. Go to Rule Testing overview for more details.
While you can configure the actions above for each threat rule, each threat type displays the count of threat rules categorized by action. Go to AI policy management for more details.
|
| Threat Type Status |
Displays the current status of a threat type, Enabled or Disabled.
Disabling a threat type disables all threat rules under it.
|
| Filtering and Grouping | Filter and/or group rules using the **Filter** (:filter:) icon or the **Group By** drop-down. |
***
## Create custom AI firewall rules
Creating an AI Firewall rule lets you define how Harnes RPA should identify and respond to specific AI-related threats in your application. Each rule specifies a threat type, detection criteria, and the corresponding action to take when Harness RPA identifies that threat. By creating these rules, you can protect your AI assets according to your requirements, ensuring that LLMs and AI endpoints are monitored and safeguarded against targeted attacks and misuse.
To create a custom AI Firewall rule, navigate to **Protection** → **Settings** → **Policies** → **AI Firewall** tab, and complete the following steps:
{% stepper %}
{% step %}
### Specify the rule details
To specify the rule details, do the following:
1. Click the **Ellipse** (:ellipsis:) icon in the top right corner of the threat type list and click **Add Rule**.
1. In the **Add Rule** pop-up dialog, select the **Threat Type** from the list of available AI threat categories.
2. In the **Add Rule: \** slide-out panel, do the following:
1. Specify the **Rule Name**.
2. (Optional) Specify the rule **Description**.
3. Based on the threat type you selected above, complete [Step 2](#specify-rule-criteria) below.
{% endstep %}
{% step %}
### Specify rule criteria
The following tabs outline the steps for specifying the rule criteria. Based on the threat type you selected while creating the rule, complete the following steps:
{% tabs %}
{% tab title="AI Input Explosion" %}
To add a new rule for **AI Input Explosion**, complete the following steps:
AI Input Explosion
1. Specify the **Rule Name**, for example, *Sample AI Input Explosion Rule*.
2. (Optional) Specify a relevant **Description** summary.
3. Select the **Environment(s)** where you wish the rule to apply.
4. Specify the **Input Characters Limit** after which Harness RPA should consider the actor a threat.
5. Select the **Scope** (All or specific AI endpoints) where you wish to apply the rule.
6. (Optional) Specify **URL Regexes** if you wish to include specific API endpoints.
7. Select the **Event Severity** you wish to apply to the identified event, for example, *High.*
8. Click **Next**.
9. Review the details you specified above and click **Submit**.
{% endtab %}
{% tab title="AI Rate Limiting" %}
To add a new rule for **AI Rate Limiting**, complete the following steps:
AI Rate Limiting Rule
1. Specify the **Rule Name**, for example, *Sample AI Rate Limiting Rule*.
2. (Optional) Specify a relevant **Description** summary.
3. Select the **Environment(s)** where you wish the rule to apply.
4. (Optional) Select the **Target** on which Traceable should apply the rule, according to your requirements:
* **AI API Entities**: The AI models based on their purpose or functionality.
* **MCP Entities**: The provider or platform behind each AI model or service.
5. Select the **Scope** where you wish to apply the rule:
* **All AI API entities**: Applies the rule to all AI API endpoints.
* **Specific AI API entities**: Applies the rule to the AI API endpoints you select.
* **All MCP entities**: Applies the rule to all MCP servers and tools, including any you add after you create the rule.
* **Specific MCP entities**: Applies the rule to the MCP servers or tools you select.
6. Traceable provides the following filters that you can select from for the above criteria:
* **Any values**: Includes all available values in the rule.
* **Matches exactly**: Includes the value(s) you specify.
* **Does not match exactly**: Includes all value(s) except the ones you specify.
* **Contains string**: Includes the value(s) that contain the string you specify.
* **Does not contain string**: Includes all value(s) except the ones containing the string you specify.
* **Matches pattern**: Includes all value(s) matching the pattern you specify.
Traceable performs an AND between the criteria above.
The values you specify for the above criteria are case-sensitive.
7. (Optional) Specify **URL Regexes** if you wish to include specific API endpoints.
8. Specify the **Rate Limiting Condition** based on which Traceable should limit the requests. This condition consists of the following parameters:
* **Access Exceed**: The number of requests after which Traceable should limit the user. For example, *50* requests.
* **Time Range**: The duration for which the limit should apply. For example, a 5-minute time window means the entity can receive up to 50 requests within that window. Once this limit is reached, Traceable limits the user.
* **Compute Condition**: The checkboxes that define how Traceable counts requests. Traceable keeps a separate counter for each value you select. The options you see depend on the **Scope** you select:
| Scope | Available compute conditions |
| --------------- | ------------------------------------------------------ |
| AI API entities | Per user, Per endpoint |
| MCP entities | Per user, Per agent, Per tool, Per server, Per session |
* **Per user**: Counts requests separately for each user.
* **Per endpoint**: Counts requests separately for each endpoint.
* **Per tool**: Counts requests separately for each MCP tool. Use this to limit access to a specific tool without affecting the rest of the MCP server.
* **Per agent**: Counts requests separately for each MCP agent.
* **Per server**: Counts requests separately for each MCP server.
* **Per MCP session**: Counts requests separately for each session.
If you select more than one checkbox, Traceable counts each combination separately. For example, if you select **Per user** and **Per server**, each user gets a separate limit on each MCP server.
9. Select the **Action to be taken for this rule** from one of the following:
1. **Monitor**: Does not block the user; it continues to monitor activity and generate events.
2. **Disable**: It disables the requests applicable to this rule.
3. **Mark for Testing**: It tests the rule without impacting traffic. Generates low-severity events and does not send notifications.
10. Select the **Event Severity** you wish to apply to the identified event, for example, *Low or Medium*.
11. Click **Next**.
12. Review the details you specified above, and click **Submit**.
### Sample Scenarios
The following scenarios show how the scope and compute conditions work together:
Cap total AI traffic
Consider a scenario where you wish to put a hard ceiling on your AI endpoints, no matter who is calling them. Select all AI API entities, set Access Exceed to 1000 and Time Range to 1 minute, and leave every compute box unchecked. Traceable keeps one counter. When Alice and Bob together pass 1000 requests in that minute, the next request is limited.
Give each user a budget on each endpoint
Consider a scenario wherea few users are running up cost on an expensive model endpoint, and you still want other endpoints left alone. Select the AI API entities, check Per user and Per endpoint, and set 200 requests in 10 minutes. Alice can send 200 to `/chat` and another 200 to `/embeddings`. Bob has the same limits. Alice’s `/chat` traffic does not count against Bob, or against `/embeddings`.
{% endtab %}
{% tab title="Model Governance" %}
To add a new rule for **Model Governance**, complete the following steps:
Model Governance Rule
1. Specify the **Rule Name**, for example, *Sample Model Governance Rule*.
2. (Optional) Specify a relevant **Description** summary.
3. Select the **Environment(s)** where you wish the rule to apply.
4. Select the **AI Model Criteria** based on which Traceable should apply the rule:
* **AI Model Types**: The AI models based on their purpose or functionality.
* **AI Vendors**: The provider or platform behind each AI model or service.
Traceable provides the following operators that you can select from, for the above criteria:
* **Any values**: Includes all available values in the rule.
* **Matches exactly**: Includes the value(s) you specify.
* **Does not match exactly**: Includes all value(s) except the ones you specify.
* **Contains string**: Includes the value(s) that contain the string you specify.
* **Does not contain string**: Includes all value(s) except the ones containing the string you specify.
* **Matches pattern**: Includes all value(s) matching the pattern you specify.
Traceable performs an AND between the criteria above.
The values you specify for the above criteria are case-sensitive.
5. Select the **Scope** (All or specific AI endpoints) where you wish to apply the rule.
6. (Optional) Specify **URL Regexes** if you wish to include specific API endpoints.
7. Select the **Event Severity** you wish to apply to the identified event.
8. Click **Next**.
9. Review the details you specified above, and click **Submit**.
{% endtab %}
{% tab title="Agent Access Control" %}
To add a new rule for [**Agent Access Control**](#user-content-fn-1)[^1], complete the following steps:
1. Specify the **Rule Name.**
2. (Optional) Specify a relevant **Description** summary.
3. Select the **Environment(s)** where you want the rule to apply.
4. Select the **Source**, which is the agent entity that the rule applies to, for example, *Agent ID, coding agent.* You can also define your own agent. For more information, see [Custom Entities](https://app.gitbook.com/o/4ctJTR2DLBok3kja4ot2/s/QiDy0ASUuFAEQLQlGRXL/settings/protection/entities#custom).
5. Select the **MCP Server** and **Tool** to which the rule applies from the following options:
1. **Entire Server**: You can configure the action on an entire MCP server
2. **Specific Tools**: You can configure the action on specific tools, for example, the *send message* tool on a Slack MCP server.
6. Select the **Action** that Traceable should take when the agent accesses the selected server or tool, for example, **Disable**, **Monitor**, or **Mark for Testing**, according to your requirements.
7. Select the **Event Severity** you want to apply to the identified event, for example, **Low.**
8. Click **Next**.
### Sample Scenarios
The following scenarios show how the scope and compute conditions work together:
Stop one user from monopolizing an MCP server
Consider a scenario where one user is flooding the GitHub MCP server, and Slack should not share that budget. Select the MCP entities, check Per user and Per server, and set 100 requests in 5 minutes. Alice can send 100 to GitHub and 100 to Slack. Bob has his own 100 on each server. When Alice passes 100 on GitHub, only her GitHub traffic is limited.
Limit a sensitive tool without limiting the rest of the server
Consider a scenario where a `create_pull_request` is sensitive, and `list_repos` on the same server should stay available. Check Per user and Per tool, and set 20 requests in 5 minutes. A can call `create_pull_request` 20 times and `list_repos` 20 times. Calls to `list_repos` do not count toward `create_pull_request`.
Limit one user per tool
Consider a scenario where you wish to stop a single chat from hammering `create_issue`, without affecting that user’s other sessions. Check Per user, Per MCP session, and Per tool, and set 10 requests in 5 minutes.
{% endtab %}
{% tab title="MCP Geo Location" %}
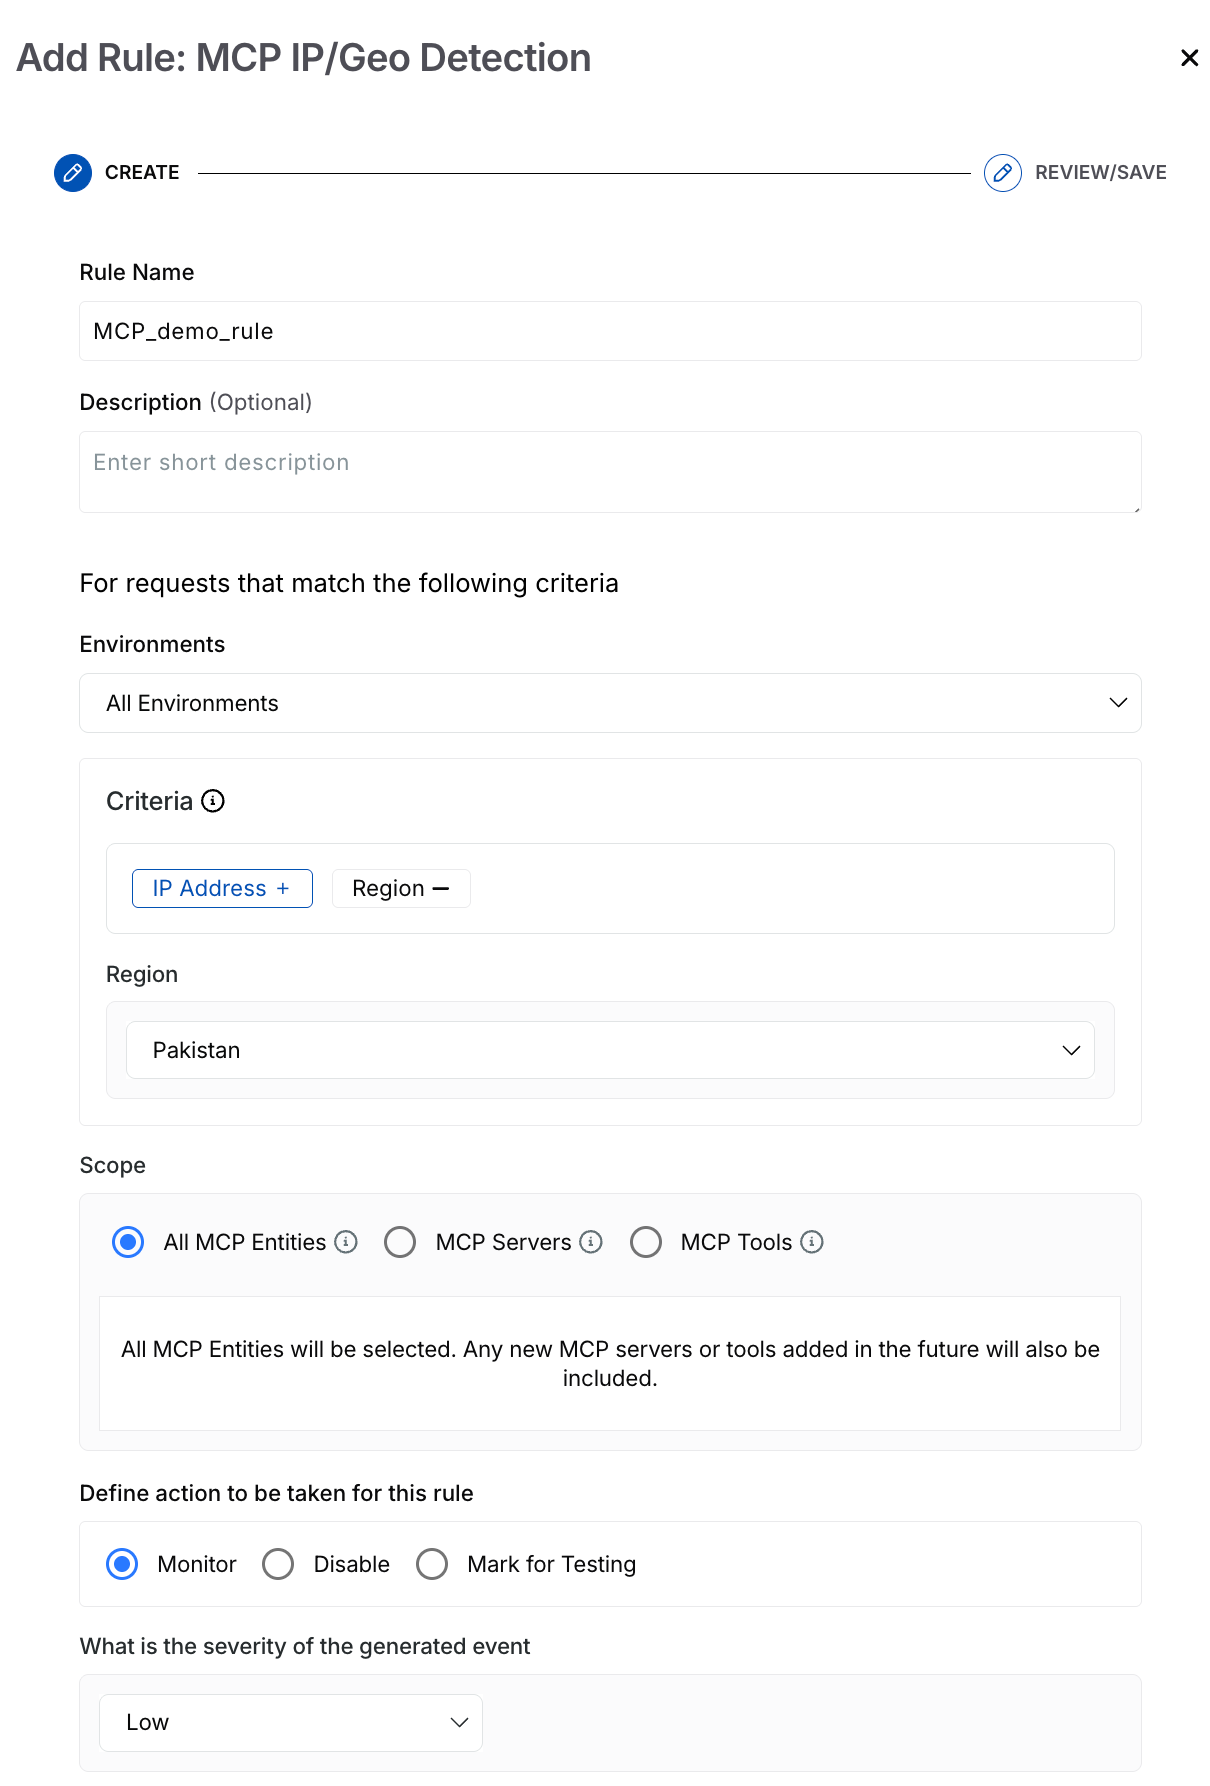
Traceable's **MCP IP/Geo Detection** rule identifies MCP requests that originate from specified IP addresses or geographic regions, so that you can monitor, flag, or block traffic from unexpected sources. To add a new rule for **MCP IP/Geo Detection**, complete the following steps:
MCP Rule
1. Specify the **Rule Name**, for example, *MCP Demo Rule*.
2. (Optional) Specify a relevant **Description** summary.
3. Select the **Environment(s)** where you want the rule to apply.
4. Select the **Criteria** based on which Traceable should apply the rule:
* **IP Address**: Matches requests based on specific IP addresses or CIDR ranges.
* **Region +**: Adds a geographic region as an additional match condition, for example, *Pakistan.*
5. If you select **IP Address**, specify the **IP Address(es)** to match against incoming MCP requests. Separate multiple addresses or ranges with commas. For CIDR ranges, ensure that the host bits are set to zero.
6. Select the **Scope** of the rule:
* **All MCP Entities**: Applies the rule to all current and future MCP servers and tools.
* **MCP Servers**: Applies the rule to selected MCP servers.
* **MCP Tools**: Applies the rule to selected MCP tools.
7. Select the **Action** that Traceable should take when a request matches the rule:
* **Monitor**: Logs the event without blocking the request.
* **Disable**: Disables the rule for the matching request.
* **Mark for Testing**: Flags the request for further review.
8. Select the **Severity** level that Traceable should assign to events generated by the rule, for example, *Low*. Use severity to prioritize the triage of matching events.
{% hint style="info" %}
Note
When you select **All MCP Entities**, Traceable automatically includes any new MCP servers or tools added after the rule is created.
{% endhint %}
{% endtab %}
{% tab title="AI Sensitive Data Protection" %}
To add a new rule for **AI Sensitive Data Protection**, complete the following steps:
AI Sensitive Data Protection Rule
1. Specify the **Rule Name**, for example, *Sample AI Sensitive Protection Rule*.
2. (Optional) Specify a relevant **Description** summary.
3. Select the **Environment(s)** where you wish the rule to apply.
4. Select the **Data Types** that Traceable should check for in the prompt.
5. Select the **Scope** (All or specific AI endpoints) where you wish to apply the rule.
6. (Optional) Specify **URL Regexes** if you wish to include specific API endpoints.
7. Select the **Action to Take** for your rule, for example, *Disable, Monitor*, or *Mark for Testing.*
8. Select the **Event Severity** you wish to apply to the identified event, for example, *Low*, *Medium*.
9. Click **Next**.
10. Review the details you specified above, and click **Submit**.
{% endtab %}
{% endtabs %}
{% endstep %}
{% endstepper %}
***
## AI policy management
Policy management in Harness RPA follows a hierarchical structure, enabling or disabling policies at the environment or granular level. You can manage components within the AI Firewall policy tab at the following levels:
AI Policy Management
* **Environment Level**: You can select the environment from the page’s top right corner and enable or disable the policy from the **Status** drop-down at the top of the tab. This enables or disables all threat types collectively on the selected environments.
* **Threat Type Level**: You can use the **Toggle** next to the threat type to enable or disable the threat rules under it. This enables or disables all the threat rules under it.
* **Threat Rule Level**: You can use the **Action** drop-down corresponding to a threat rule to enable (*Monitor*), disable (*Disable*), or mark it for testing (*Mark for Testing*).
While enabling the AI Firewall policies at the environment level enables all threat types, you can also enable or disable the individual threat types or rules according to your requirements. Similarly, when you enable a threat type, you can manage the rules independently.
{% hint style="info" %}
Any change at either of the above levels in All or specific environments is called an override. Go to [Overrides](https://developer.harness.io/web-application-and-api-protection-waap-discovery-discovery-discovery-discovery/protection/settings/web-application-firewall-policies/profiles-and-overrides-in-waf-policies.md#overrides) for more details.
{% endhint %}
***
## Actions on AI policies
Harness RPA allows you to carry out various actions on the threat rules available in the following threat types:
* AI Sensitive Data Protection
* Model Governance
* Agent Access Control
* AI Rate Limiting
* AI Input Explosion
The following table explains the actions you can perform on the predefined and custom threat rules:
| Action | Description |
| ---------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **View** | View the rule details without modifying them. |
| **Edit** | Modify the details specified in the rule. |
| **Reset** (pre-defined rules only) | Reset the rule to the default configuration specified by Harness RPA. |
| **Delete** (custom rules only) |
Delete the rule.
Deleted rule(s) cannot be restored.
|
{% @harness-feedback/feedback %}
[^1]: Agent Access Governance flags requests made by specific AI agents, such as coding agents, to MCP servers, tools, or LLMs that the agent is not permitted to use.

 1. In the **Add Rule** pop-up dialog, select the **Threat Type** from the list of available AI threat categories.
2. In the **Add Rule: \